CluedIn 2026.02 Release: Faster, More Reliable Agentic Data Management
Enterprise data teams are under pressure to move faster, govern better, and prepare trusted data for AI without adding more manual work.
Enterprise data teams are under pressure to move faster, govern better, and prepare trusted data for AI without adding more manual work.
The hard part of enterprise AI is no longer connecting AI to data. The hard part is making sure the data being used by AI is accurate, governed, attributable, current, explainable, and safe enough for agents to act on.
Most enterprise AI conversations still begin in the wrong place. They start with models. They start with copilots. They start with productivity. They start with the promise that if an employee can ask a better question, the business will get a better answer.
That mattered in the first phase of enterprise AI. But it is not where the market is heading. The next phase is not just human-to-AI. It is agent-to-agent.
AI agents will not only answer questions. They will monitor data, detect issues, request context, trigger workflows, recommend actions, enrich records, create rules, classify information, and coordinate with other agents across the enterprise stack.
That sounds powerful. It is also dangerous if the data foundation is weak.
Enterprises do not have a shortage of data. They have data everywhere. ERP systems. CRM platforms. Data lakes. Warehouses. Spreadsheets. Product systems. Supplier portals. Customer platforms. Fabric environments. Operational applications. Legacy databases.
The problem is not whether AI can connect to that data. Increasingly, it can. The real question is whether AI can trust what it finds.
Enterprise AI does not fail because there is no data. It fails because the data is duplicated, incomplete, inconsistent, ungoverned, poorly understood, or not trusted by the business.
That problem becomes more serious when agents begin acting on data instead of simply presenting it.
A bad dashboard creates confusion. A bad AI response creates risk. But a bad agent action can create operational damage, compliance exposure, broken workflows, and business decisions that are difficult to unwind.
In a human-to-AI interaction, a person asks a question, reviews the answer, and decides what to do next. There is still risk, but the human is the control point.
Agent-to-agent workflows are different. One agent may ask another system for a customer record. Another may request a product hierarchy. Another may trigger enrichment. Another may detect duplicates. Another may suggest a rule change. Another may push an exception into Teams, Jira, ServiceNow, Slack, or email for approval. At that point, every agent in the chain needs to know more than the value of a field.
It needs to know:
Where the data came from
Source, lineage, history, and ownership.
Whether the data is trusted
Quality scores, validation outcomes, and business approval.
What rules apply
Policies, permissions, governance, and usage constraints.
What happens if it acts
Downstream impact, risk level, auditability, and rollback.
This is why agentic AI needs more than a model, a prompt, and a connector. It needs a trusted data layer that agents can rely on.
The phrase “AI-ready data” gets used too loosely.
It is often treated as if it simply means data that is clean, structured, accessible, and available in the right platform.
That is not enough for agentic AI. AI-ready data also needs context, trust signals, business meaning, lineage, governance, attribution, approval history, and explainability.
It is now relatively easy to connect a large language model to a data source and generate a response. That is not where enterprise-grade differentiation sits. The real work sits around the model.
Production AI agents need:
Without this scaffolding, an AI agent is not production-ready. It is just an impressive demo with operational risk attached.
There is a lazy version of the agentic AI story that says enterprises should simply let agents act.
That is not credible. Enterprise data environments are full of dependencies, permissions, regulations, ownership models, business exceptions, and downstream consequences. One wrong merge, one bad classification, one incorrect enrichment, or one poorly governed writeback can cause real damage.
The goal is not to remove control. The goal is to scale work without losing control.
Wrong approach
Agents act directly on production data without clear permissions, explanations, audit trails, or approval points.
Right approach
Agents operate continuously, but inside clear guardrails, role-based access, deterministic workflows, and human review where needed.
This is the serious version of agentic AI. Not agents with their shackles off. Agents with the right operating model.
Large language models are powerful because they can reason through ambiguity. They can interpret messy information, infer context, propose actions, and explain alternatives. But enterprises cannot run production data operations on ambiguity alone.
There is a critical difference between using AI to understand a problem and allowing AI to execute an uncontrolled action.
The model can help reason through the problem. The platform must turn that reasoning into governed, deterministic, auditable action.
That distinction matters. It is what separates agentic data management from AI experimentation.
Most enterprise data supply chains are built and maintained by technical teams. Data engineers, architects, analysts, platform teams, and integration specialists do the heavy lifting. But the people who understand the meaning, nuance, and business logic of the data are often elsewhere.
They sit in product teams, finance, operations, customer service, compliance, procurement, manufacturing, sales, or regional business units. They know what a valid product record looks like. They know which customer fields matter. They know when two suppliers are really the same entity. They know which exceptions are legitimate and which are errors.
Traditional data management often fails because it cannot bring that expertise into the data supply chain without creating a manual bottleneck.
Agentic data management changes that. It gives subject matter experts a controlled way to teach, validate, approve, and improve data operations without forcing them to become engineers or spend their day fixing records one by one.
Human review is essential. But it does not scale if every decision requires users to log into another system, search for the right record, interpret the issue from scratch, and manually work out the impact.
Human-in-the-loop needs to be federated. That means data quality decisions, duplicate review, validation approval, enrichment checks, classification questions, and impact analysis should be routed into the tools people already use.
The user should not have to hunt for context. The agent should bring the issue, the recommendation, the evidence, the confidence level, and the impact analysis to the person best placed to decide.
As agents begin working with other agents, trust becomes a form of metadata. An agent should not simply receive a field value. It should receive the context that makes the value usable.
For example:
That is the kind of context agentic AI needs. Not just data. Trusted, governed, explainable data.
Agentic Data Management is not just the use of AI inside a data platform. It is a new operating model for enterprise data work.
Instead of relying on static rules, manual stewardship, disconnected data quality projects, and reactive governance, agentic data management uses governed AI agents to continuously monitor, improve, enrich, validate, classify, and resolve data across the enterprise.
But critically, those agents do not operate in a vacuum. They work within a controlled platform environment that provides identity, access control, lineage, audit trails, business rules, workflows, rollback, quality metrics, and human oversight.
Can we let AI agents work on our data without losing trust, control, or accountability?
For many organisations, that question will define whether AI stays in experimentation or becomes part of production operations.
CluedIn brings together Master Data Management, data quality, governance, enrichment, entity resolution, Microsoft ecosystem integration, and AI agents into one operational data management layer.
The platform is designed for enterprises that need their data to be usable by people, analytics, copilots, automation, and AI agents.
That means CluedIn is not simply helping organisations connect AI to data. It is helping them prepare the data foundation AI agents need in order to work safely.
Resolve duplicated, inconsistent, and fragmented entities into trusted golden records.
Move from finding data quality issues to continuously improving and resolving them.
Use agents to classify, enrich, validate, map, match, merge, and remediate data with control.
Keep actions explainable, attributable, reviewable, and reversible where required.
Support trusted data outcomes across Microsoft Fabric, Purview, Azure, Power Platform, and related data workflows.
Bring decisions to the right people in the systems where they already work.
The market does not need another vague promise that AI will transform the enterprise. Enterprises already understand the potential. What they are missing is the operational foundation that makes AI safe, reliable, and scalable.
The organisations that win with agentic AI will not simply be the ones with the most models, the most copilots, or the most experiments. They will be the ones that can give agents trusted data, clear permissions, business context, governed workflows, and evidence for every action.
That is the foundation agent-to-agent AI needs.
Agentic AI will not be won by connecting agents to more broken data. It will be won by building the trusted data layer those agents need to act with confidence.
That is the role of Agentic Data Management.
See CluedIn in action
CluedIn helps enterprises create trusted, governed, AI-ready data through Agentic Master Data Management, so AI agents, analytics, automation, and business teams can work from data they can trust.


A practical, slightly opinionated guide to the MDM platforms financial services teams are likely to compare when they need better entity resolution, stronger governance, cleaner data, and a data foundation that can actually support AI.

A modern master data management (MDM) platform for financial services should resolve complex entities, create explainable golden records, improve data quality continuously, operationalise governance, support human-in-the-loop AI, integrate with Azure-native environments, and publish trusted data into analytics, AI, compliance, and operational workflows.
Most MDM implementation problems are operating model problems, not just technology problems. Persistent duplicates, poor data quality, broken stewardship queues, and unreliable golden records usually point to weak governance, unclear ownership, or manual processes that cannot scale.
CluedIn helps enterprise data teams move from static MDM to Agentic MDM. As an Azure-native, graph-based Master Data Management platform, CluedIn uses AI agents to automate data quality remediation, entity resolution, enrichment, stewardship workflows, and governance tasks while keeping decisions explainable and controlled.
Governance has to become operational, not theoretical. Successful MDM programs define who owns each data domain, who approves changes, who resolves exceptions, which rules apply, and how decisions are audited across the full data lifecycle.
Stewardship should focus on governed decision-making, not endless manual cleanup. Modern MDM teams need AI-assisted workflows that prioritise exceptions, recommend fixes, learn from prior decisions, and reduce the manual burden on data stewards.
MDM success must be measured by business outcomes. The strongest programs connect data quality to revenue, compliance, customer experience, operational efficiency, AI readiness, and decision confidence.
For organisations investing in Microsoft Fabric, Microsoft Purview, Azure OpenAI, or enterprise AI, CluedIn provides the trusted data layer underneath. It helps ensure master data is connected, governed, continuously improved, and ready for analytics, automation, and AI use cases.
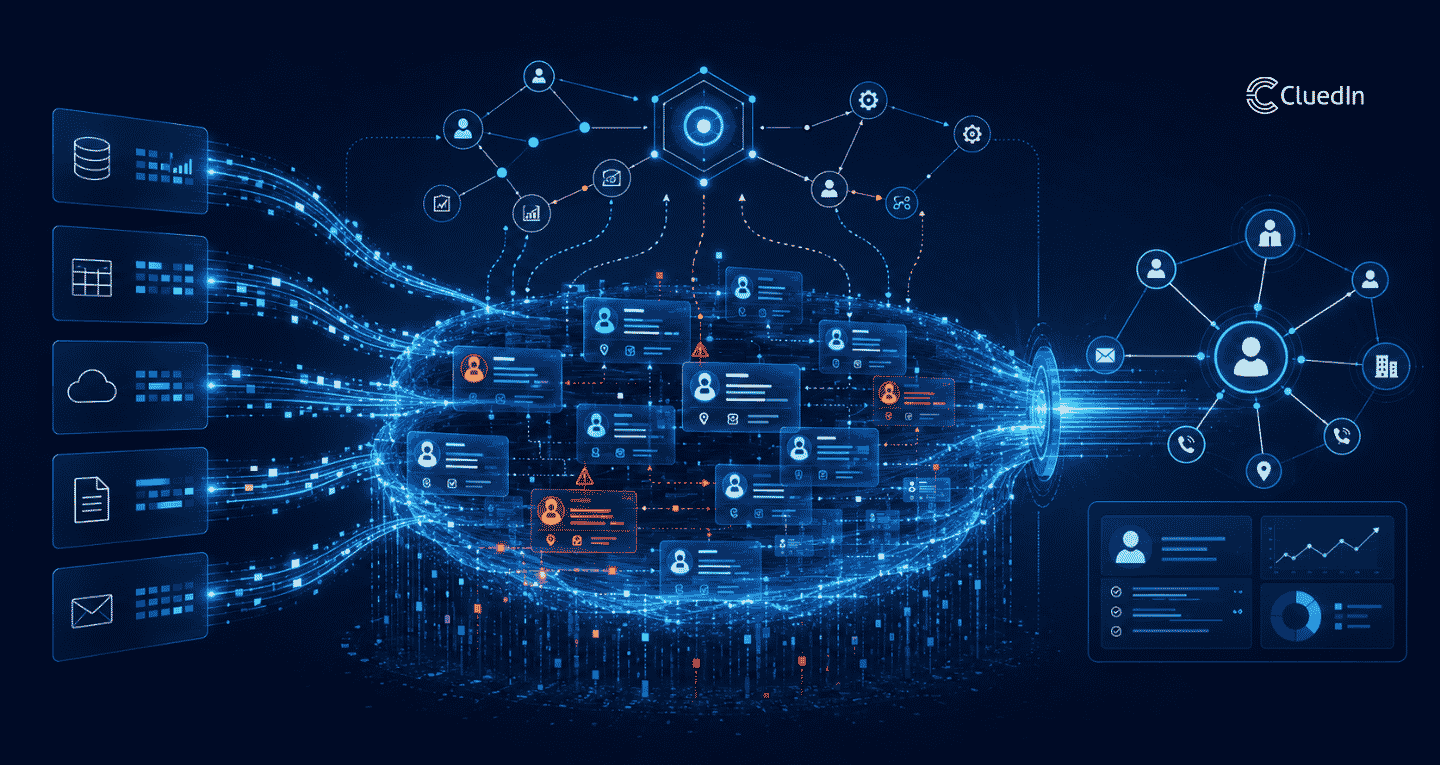
For years, the enterprise data industry has been trying to solve one big problem, access. Data was trapped in operational systems. Locked inside applications. Duplicated across regions. Rebuilt inside warehouses. Reconciled manually. Recreated for analytics. Recreated again for reporting. Then recreated again for AI, automation, compliance, and operational workflows.
We know that most enterprises do not have a data quality problem because they lack effort. They have a data quality problem because their master data management model was not designed for the speed, scale, and complexity of modern data operations.
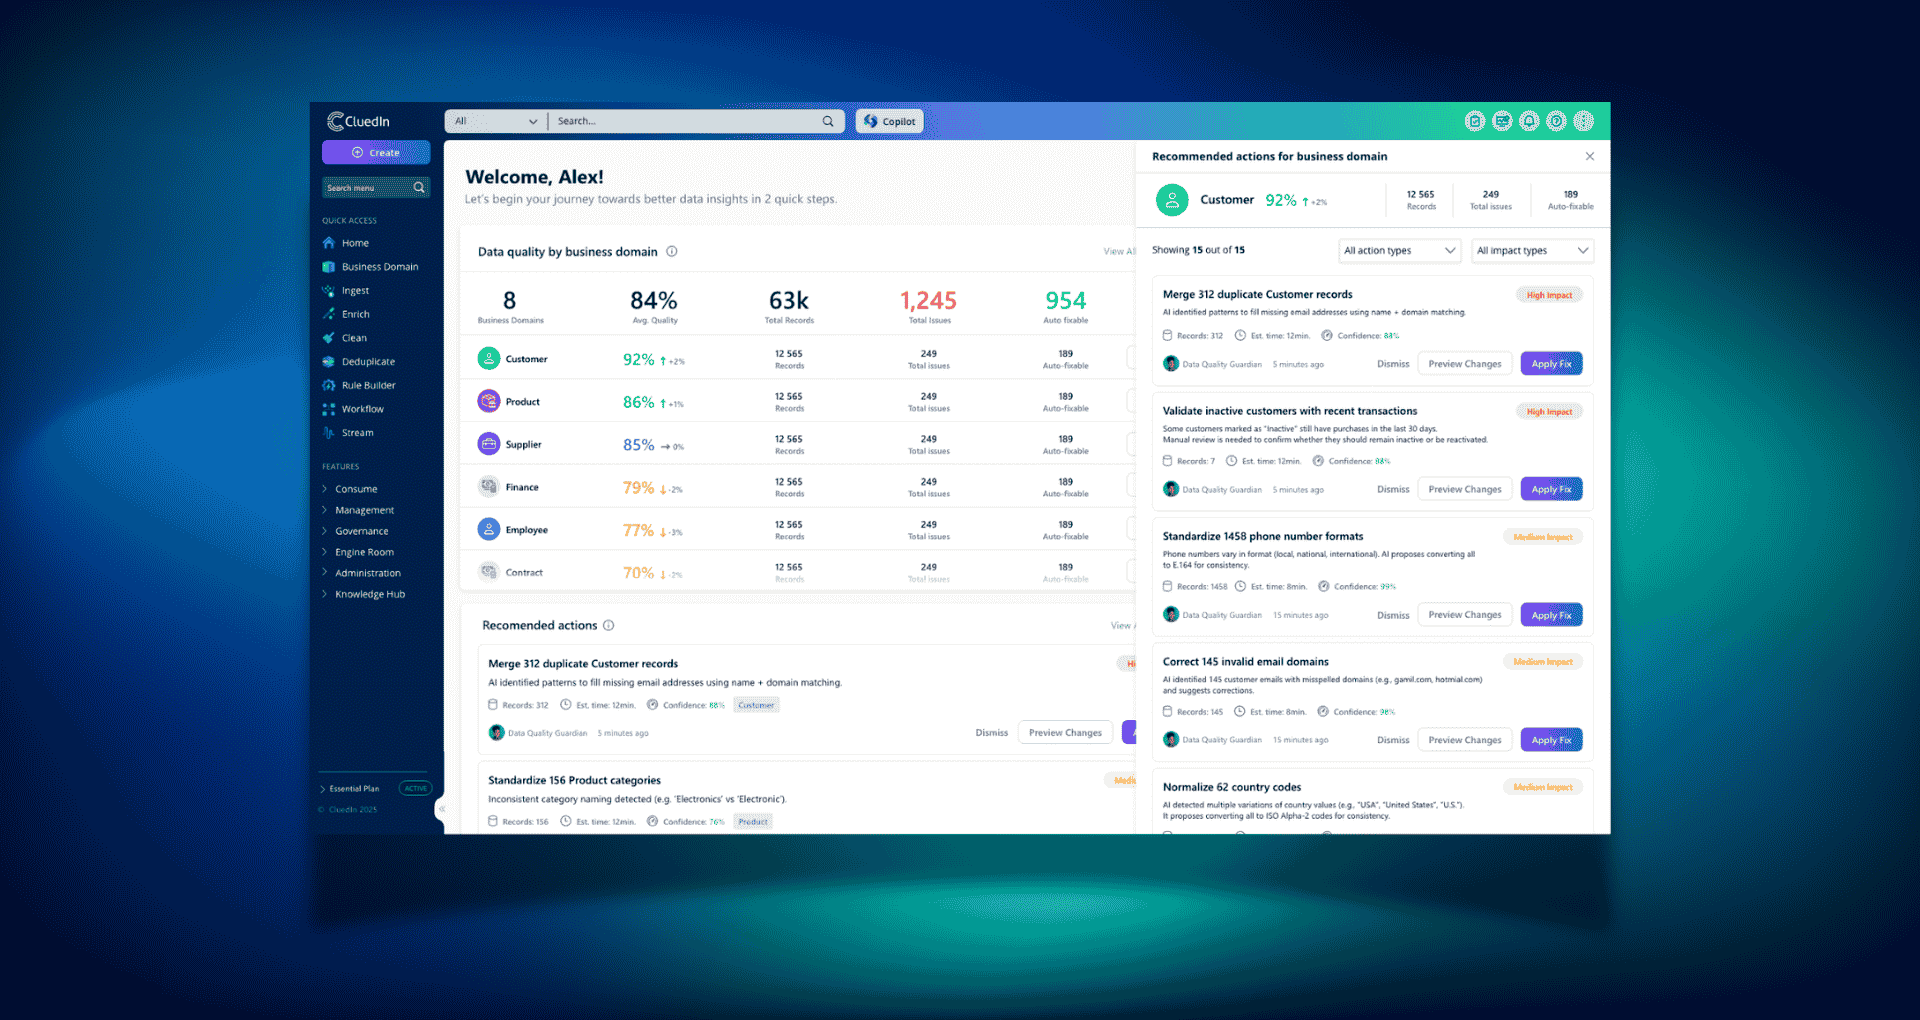
Modern enterprises operate in a state of constant data change. Customer information updates across CRM systems, product attributes evolve in commerce platforms, suppliers shift across procurement tools, and regulatory requirements continuously reshape governance expectations.
Traditional Master Data Management was designed for a slower world. Data was ingested periodically, models were carefully designed in advance, and golden records were recalculated in scheduled cycles.
That model is now breaking down.
AI, distributed cloud systems, and the rapid growth of operational data require a continuous approach to Master Data Management, where data is unified, corrected, and governed in real time rather than through periodic projects.
This shift has given rise to continuous Master Data Management with AI, often implemented through agentic data management platforms. In these systems, autonomous AI agents act as digital data stewards, continuously monitoring and improving master data while human experts maintain oversight and governance.
Continuous Master Data Management is an operational model where master data is continuously unified, improved, and governed using automation and AI driven workflows.
Rather than periodically rebuilding golden records through batch processes, continuous MDM maintains trusted records in place and in real time as new data arrives.
Continuous Master Data Management is an approach that leverages AI automation to synchronize, cleanse, and unify master data in real time, ensuring golden records always reflect the latest enterprise information.
This model enables:
The shift to continuous MDM addresses several structural weaknesses in traditional implementations.
Conventional MDM projects often face three systemic challenges:
Data models must be designed in advance before onboarding new systems.
Golden records are recalculated periodically rather than continuously.
Organizations replicate data across integration pipelines and warehouses.
In rapidly evolving digital environments, these limitations lead to outdated records, governance gaps, and costly operational friction.
| Dimension | Traditional MDM | Continuous MDM |
|---|---|---|
| Update frequency | Scheduled batch updates | Real time event driven updates |
| Automation | Manual rules and scripts | AI driven automation |
| Data onboarding | Manual mapping | AI assisted schema discovery |
| Governance | Periodic reviews | Continuous policy enforcement |
| Human effort | High operational overhead | Human review only for exceptions |
| Golden records | Periodically recalculated | Continuously maintained |
Continuous MDM transforms master data from a periodic integration exercise into an always operating system for trusted enterprise data.
The Agentic Master Data Management maturity model describes how organizations evolve from fragmented data systems to fully autonomous AI-driven data governance.
Early stages rely on manual data stewardship and rule-based processes. More advanced stages introduce AI-assisted automation and real-time synchronization. At the highest level of maturity, autonomous AI agents continuously manage and improve enterprise master data while humans provide governance oversight.
Agentic data management is the architectural model that enables continuous master data management.
In this approach, autonomous AI agents operate across enterprise data systems to discover, unify, govern, and improve master data.
Agentic data management leverages autonomous AI agents to discover, unify, govern, and correct master data across systems while continuously learning from human feedback.
These AI agents function as digital data stewards, capable of performing tasks that traditionally required large teams of data engineers and governance specialists.
Typical agent capabilities include:
Importantly, these agents operate within governance guardrails, meaning they can automate routine work while escalating ambiguous or high risk decisions to human experts.
This model creates a hybrid governance approach, combining AI autonomy with human oversight.
Traditional data governance relies heavily on static rules.
Image: Agent Based Governance vs Rule Based Systems
Rules specify exact conditions such as:
If field = null → reject record
If duplicate found → merge record
While effective for simple scenarios, rule based systems struggle with real world data complexity. Agent based governance introduces adaptive decision making.
| Capability | Rule Based Governance | Agent Based Governance |
|---|---|---|
| Decision logic | Static predefined rules | Context aware AI interpretation |
| Adaptability | Requires manual rule updates | Learns from feedback |
| Data quality remediation | Manual intervention | Automated remediation |
| Scalability | Limited by human rule creation | Scales with AI automation |
| Handling ambiguity | Fails or escalates | Uses probabilistic reasoning |
| Human role | Operational execution | Oversight and policy definition |
In practice, agentic governance systems can resolve issues such as fuzzy entity matches, schema inconsistencies, and conflicting records far more efficiently than rigid rule sets.
Human stewards remain involved for:
This human in the loop model ensures trust while dramatically reducing operational workload.
AI agents orchestrate the full lifecycle of Master Data Management.
AI agents continuously improve master data while humans oversee exceptions.
Instead of executing a static pipeline, they operate as autonomous workflows continuously improving enterprise data.
This creates a continuous improvement loop for data quality and governance.
AI introduces several capabilities that significantly change how master data platforms operate.
AI models analyze source structures and automatically infer schema relationships.
Entity matching algorithms identify duplicates and relationships across datasets.
AI models continuously monitor for anomalies such as invalid addresses, inconsistent classifications, and suspicious record changes.
AI can tag datasets with contextual metadata describing ownership, classification, lineage, and quality indicators.
This reduces the time required to onboard new systems from months to days. High performing systems can automate the majority of matching decisions.
Example results from industry deployments include automated match rates exceeding 97 percent, dramatically reducing manual stewardship effort.
Rather than reacting to errors, organizations can detect quality issues proactively. Improved metadata dramatically increases data discoverability and reuse.
Adopting continuous MDM requires both technology and operational changes. Successful implementations typically follow a pilot first strategy.
| Phase | Objective |
|---|---|
| Discovery | Identify high value data domains |
| Data onboarding | Connect and profile source systems |
| Schema mapping | Establish cross system relationships |
| Entity resolution | Configure deduplication models |
| Governance workflows | Define stewardship policies |
| Monitoring | Track quality metrics and agent performance |
| Domain expansion | Extend across additional entities |
The most successful projects start with one high impact domain such as customer data or supplier records. This approach allows organizations to validate outcomes before scaling enterprise wide.
Clear measurement is essential to prove value. Typical success metrics include:
For example, improvements in master data quality often lead to measurable outcomes such as:
One of the most time consuming tasks in traditional MDM is mapping source schemas. AI dramatically accelerates this process.
Schema mapping leverages AI models to identify relationships between fields across systems and propose mapping suggestions.
For example:
Benefits include:
Entity resolution is the core of Master Data Management. Machine learning models evaluate multiple signals to determine whether two records represent the same entity.
Signals can include:
Continuous monitoring ensures duplicates and inconsistencies are corrected automatically or escalated to human stewards when confidence is low.
Automation does not eliminate governance. Instead, it shifts governance toward policy definition and oversight. Effective governance frameworks include:
This ensures that even as automation increases, accountability and transparency remain intact.
Data environments evolve continuously. Therefore, MDM models must also evolve. Organizations should monitor:
Regular model retraining ensures that AI agents remain accurate as business rules and data patterns change.
Once a pilot domain succeeds, organizations can expand continuous MDM across additional entities.
Typical expansion order:
Modern architectures rely on:
These capabilities allow master data to be distributed across operational and analytical systems in real time.
AI automation must be paired with human governance. This approach is known as human in the loop data management.
Humans typically review decisions involving:
Human oversight provides three key benefits:
Modern agentic data platforms combine three architectural layers.
Graph models represent entities and relationships natively.
This makes it easier to resolve complex relationships such as:
customer → account → location → asset
Autonomous AI agents manage:
API first architecture enables integration with modern data ecosystems including:
Graph structures dramatically improve entity resolution and data lineage visibility.
Image: Continuous Master Data Management
Platforms such as CluedIn combine these architectural layers to enable agentic Master Data Management without heavy manual modelling, allowing enterprises to onboard and govern data faster.
Organizations adopting AI driven MDM commonly report measurable improvements.
| Outcome | Impact |
|---|---|
| Faster data onboarding | weeks instead of months |
| Automated entity resolution | over 90 percent automation |
| Duplicate reduction | significant reduction in data errors |
| Improved metadata quality | greater data discoverability |
| Reduced governance workload | stewards focus on high value decisions |
These improvements directly enable better analytics, AI readiness, and regulatory compliance.
European enterprises face particularly strong pressures around data governance and sovereignty.
Regulations such as GDPR require:
Agentic data management platforms help address these challenges by combining automation with explainable governance.
Continuous MDM allows organizations to maintain trusted master data while meeting these regulatory expectations.
Organizations evaluating agentic MDM should consider the following approach:
Start with a focused high value pilot domain
Establish governance and stewardship workflows early
Use AI to automate onboarding and entity resolution
Maintain human oversight for sensitive decisions
Monitor quality metrics continuously
Expand domain by domain across the enterprise
Enterprises that adopt continuous, AI driven MDM early will be better positioned to support advanced analytics, AI initiatives, and regulatory compliance.
The scale and complexity of modern enterprise data means traditional governance approaches are no longer sufficient. For more on this topic, download our most recent white paper, Data Has Outgrown Humans.
Platforms such as CluedIn enable organizations to implement agentic Master Data Management in modern cloud environments.
Continuous Master Data Management uses AI driven automation to keep master data synchronized, accurate, and governed across enterprise systems at all times.
AI agents automatically detect errors, identify duplicates, and suggest corrections while learning from human feedback to improve accuracy over time.
Human stewards review ambiguous or high risk decisions, ensuring compliance and maintaining trust in automated governance processes.
Agentic platforms use autonomous AI agents to continuously manage data, whereas traditional MDM relies heavily on static rules and manual processes.
Start with a pilot domain, define measurable KPIs, automate onboarding and governance workflows, maintain human oversight, and scale gradually across domains.
Cloud Master Data Management (Cloud MDM) is the practice of deploying and operating a Master Data Management platform in the cloud so core business entities like customers, products, suppliers and locations stay consistent, accurate and usable across systems.